
Meta Unveils Wonder AI Models: Pursuing the Frontier with Active Memory and Dynamic Focus

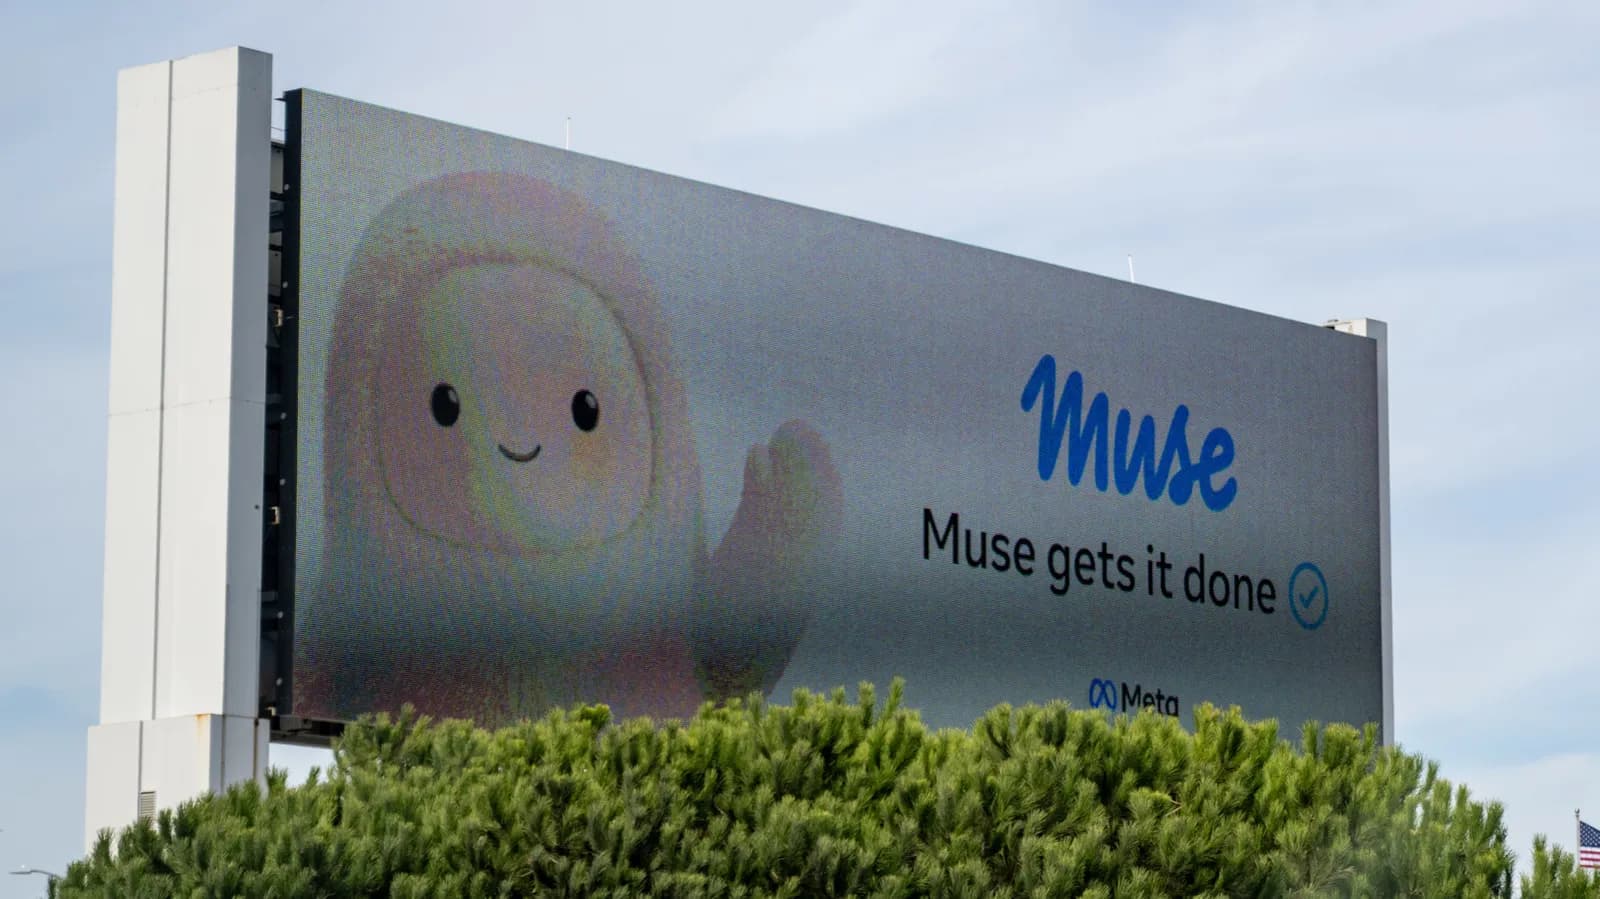
The battle for dominance at the frontier of artificial intelligence has intensified as Meta announces its latest generation of foundation systems, dubbed the Wonder models. Long positioning itself as a challenger seeking parity with proprietary industry leaders like OpenAI, Anthropic, and Google, Meta now asserts that its newest systems close the performance gap entirely. Central to this claim is a departure from conventional static transformer execution, driven by two headline architectural mechanisms: active memory and active focus. These capabilities aim to fundamentally reshape how models retain state across sprawling workflows and dynamically prioritize information during complex multi-step reasoning.
As large language models encounter the practical limitations of expanding context windows—often plagued by memory degradation, runaway compute costs, and the infamous "needle-in-a-haystack" retrieval failures—Meta's shift points toward a more adaptive cognitive paradigm. Rather than merely scaling parameter counts or inflating token limits, the Wonder models focus on intentional processing. For software engineers, researchers, and enterprise architects, this progression highlights a transition from passive token-prediction engines to structured computational entities capable of sustained, agentic execution.
The Core Innovation: Deconstructing Active Memory
Traditional transformer architectures treat memory as an ephemeral, sliding window of context tokens. Even as context windows have ballooned to millions of tokens in recent experimental releases, standard attention mechanisms remain computationally expensive and fundamentally passive. The model computes attention over everything within the window indiscriminately, leaving the burden of coherence and long-term state maintenance on complex prompt engineering, external retrieval-augmented generation (RAG) pipelines, or vector databases. When sessions conclude or context shifts, that immediate working memory evaporates.
Meta’s introduction of active memory directly challenges this limitation. Instead of relying purely on passive token storage, active memory allows the neural network to synthesize, update, and manage an internal working state over time. This approach operates much like human working memory, where vital concepts, ongoing constraints, and intermediate conclusions are actively cataloged and refreshed while tangential details are discarded. By deliberately writing to and reading from an integrated state representation, the model mitigates the high computational penalty of recalculating full self-attention across massive histories.
For developers building interactive software, this mechanism offers profound advantages. It bridges the gap between fast, short-term prompt execution and heavy external vector databases. An architecture equipped with active memory can autonomously maintain continuity across prolonged interactions, track mutable variables in complex code generation environments, and preserve project-level context without requiring developers to continuously re-inject thousands of boilerplate tokens with every API call.
Refining Attention: How Active Focus Directs Compute
Alongside persistent memory, Meta has introduced active focus, an algorithmic refinement aimed at how the model distributes its attention during inference. In standard inference pipelines, every token generated typically commands a uniform compute budget through standard feedforward and attention layers. While mixture-of-experts (MoE) architectures selectively route tokens through specialized sub-networks, they still largely operate on fixed activation paths per token rather than dynamically tuning cognitive effort based on problem complexity.
Active focus allows the Wonder models to dynamically throttle and direct attention toward critical problem vectors. When faced with high-entropy reasoning tasks, algorithmic puzzles, or intricate code syntax, the system can concentrate compute selectively, isolating critical variables and sub-problems while minimizing overhead on trivial narrative connective tissue. This represents a pragmatic synthesis of internal reasoning chains and targeted attention masks, allowing the model to hone in on key dependencies without getting derailed by extraneous background noise.
In practical development scenarios, this capability directly addresses common model failure modes such as hallucinated function parameters, missed edge cases, and catastrophic drift in logic-heavy prompts. By concentrating active focus on pivotal structural constraints—such as API schema contracts, type definitions, or complex mathematical invariants—the system achieves higher fidelity output where precision matters most, without incurring unnecessary compute overhead across straightforward text generation.
Closing the Frontier Gap: Meta’s Strategic Positioning
Meta’s declaration that it has caught up to the frontier marks an important inflection point in the broader AI ecosystem. For much of the generative AI boom, the upper echelon of raw benchmark performance was fiercely defended by closed-source pioneers. Meta’s previous flagship initiatives earned immense goodwill and widespread adoption by providing openly accessible weights, but they often trailed closed frontier systems by several months in raw reasoning capability and multimodal depth.
With the Wonder series, Meta seeks to dismantle the perception that open and accessible architectures are perpetually one step behind proprietary offerings. By prioritizing efficiency-driven innovations like active memory and focus, Meta is challenging the prevailing assumption that frontier-class intelligence can only be achieved through brute-force scaling of clusters and proprietary compute stacks. This move exerts significant competitive pressure on closed model providers, whose enterprise value propositions rely heavily on maintaining an insurmountable capability moat.
Furthermore, Meta’s strategic trajectory reinforces its broader business objectives. By advancing state-of-the-art AI infrastructure and distributing high-performance models across consumer and enterprise applications, the company strengthens its ecosystem, commoditizes the underlying foundation layer, and accelerates community-driven optimization across open-source toolchains, compilers, and inference runtimes.
The Developer Impact: From Static Prompts to Autonomous Agents
For software engineers and system architects, the technical advancements in the Wonder models signal a decisive evolution in autonomous agent design. The current paradigm of autonomous agents relies heavily on fragile scaffolding: orchestrators, recursive prompt chains, external memory scrapers, and heuristic tool-selection routines. These systems frequently break down when long-running workflows cause context overflow, leading to hallucination or catastrophic amnesia.
The combination of active memory and active focus directly targets these architectural friction points. Consider the practical challenges of automated code refactoring across a large-scale repository:
- State Continuity: Active memory allows an agent to maintain the overarching dependency graph and architectural guidelines across hundreds of file modifications without needing exhaustive prompt re-hydration.
- Targeted Attention: Active focus enables the model to zero in on breaking changes, type mismatches, and critical interfaces during code analysis, ignoring irrelevant implementation boilerplate.
- Lower Orchestration Overhead: By handling state synthesis natively within the model weights, engineers can drastically simplify their agentic middleware, reducing reliance on brittle custom parsing layers.
As these primitives become standard features rather than ad-hoc engineering workarounds, the barrier to building robust, long-running digital assistants and automated engineering pipelines will drop significantly. Developers will be able to treat foundation models as stateful computing runtimes rather than purely stateless evaluation functions.
Inference Realities and Infrastructure Trade-Offs
While the architectural promises of active memory and dynamic focus are compelling, they introduce new complexities for infrastructure teams and platform engineers. Deploying traditional transformer models is already an operational challenge, requiring precise memory allocation for Key-Value (KV) caches, aggressive quantization, and sophisticated batching strategies like continuous batching and PagedAttention.
Introducing dynamic, stateful memory constructs inherently complicates inference optimization. If a model maintains an evolving internal state representation across calls, serving layers must determine how and where that state is serialized, cached, and moved between GPU clusters. Storing active memory states across distributed environments could introduce I/O bottlenecks and complicate serverless deployment models, which thrive on stateless horizontal scaling.
Similarly, dynamic focus mechanisms that vary compute expenditure per token challenge standard latency profiling and service-level agreements (SLAs). In high-throughput production environments, unpredictable inference times per query can complicate load-balancing and resource provisioning. Engineering teams will need to evaluate whether the qualitative gains in reasoning accuracy justify the increased complexity of managing stateful inference pipelines at scale.
The Road Ahead: The Era of Adaptive Computing
Meta's unveiling of the Wonder models underscores a fundamental truth about the future of artificial intelligence: the path to genuine frontier intelligence will not be paved by parameter scaling alone. As raw pre-training data hits diminishing returns and compute budgets face physical and economic ceilings, the focus of AI research is decisively shifting toward architectural efficiency, algorithmic dynamism, and structured reasoning.
Whether the Wonder models maintain their claimed frontier parity across independent developer evaluations remains to be seen. However, the conceptual framework they champion—models that actively decide what to remember, what to discard, and where to concentrate their cognitive resources—represents the clear direction of the discipline. As the broader community begins to stress-test these capabilities, the boundary between static language generation and truly autonomous, adaptive computing will continue to dissolve.
Source: engadget.com