
Meta Reclaims Frontier AI Ground with New Model Built for Agent Reliability

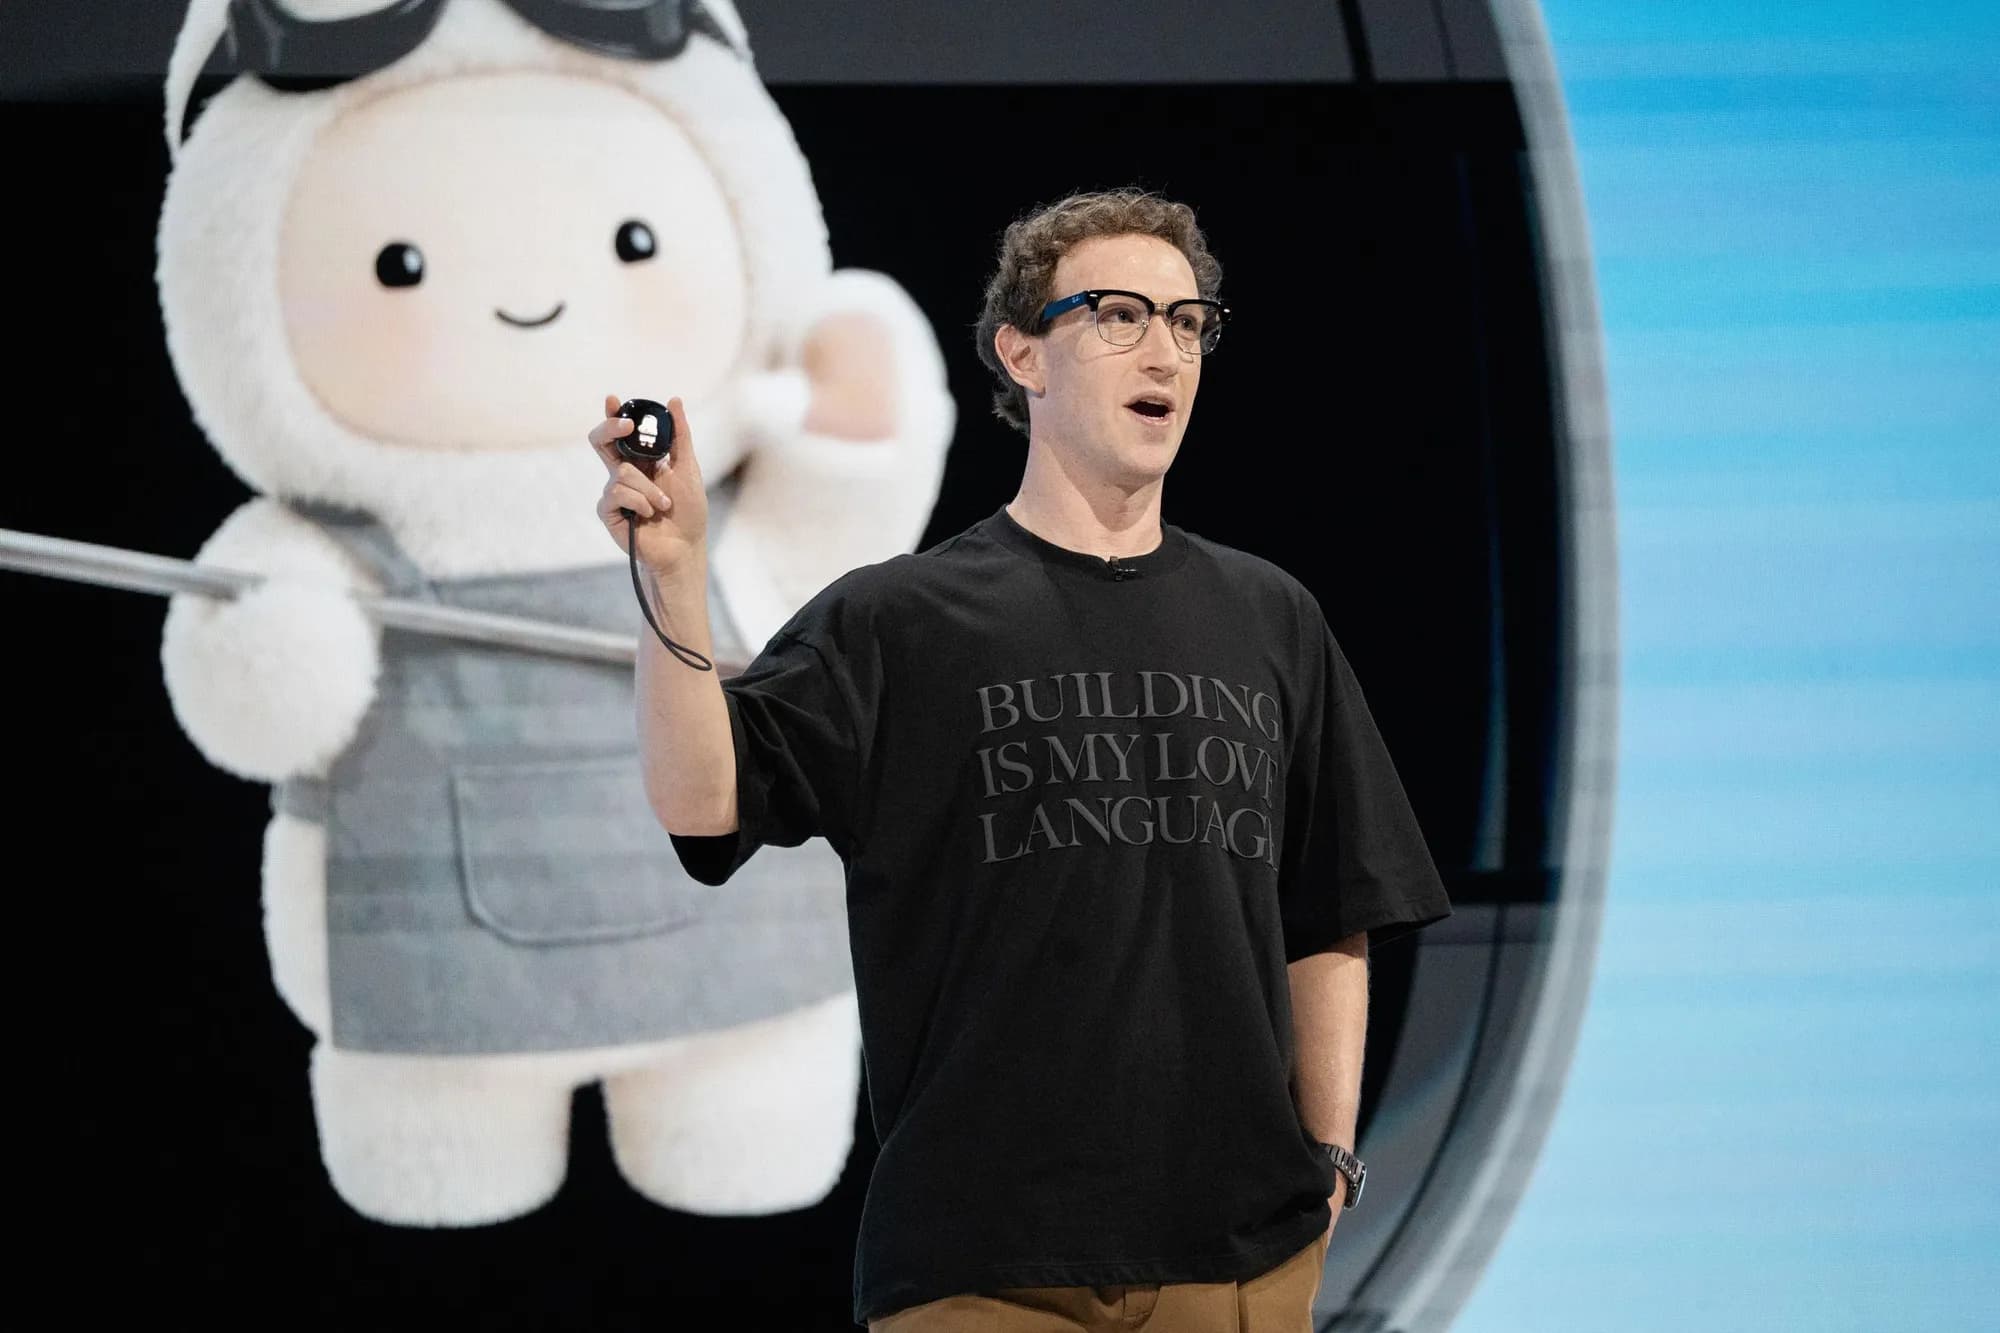
The battle for dominance at the absolute frontier of artificial intelligence has intensified once again. Meta has stepped forward with its most ambitious model yet, aiming squarely at the top-tier systems fielded by proprietary competitors. While raw benchmark performance and parameter counts have traditionally dominated headlines during frontier releases, this latest milestone signals a critical shift in strategic focus: practical execution and system-level dependability. Rather than merely optimizing for creative prose or broad conversational capabilities, Meta has engineered deliberate mechanisms designed to keep multi-step autonomous agents grounded, predictable, and aligned with intended operating boundaries.
The Relentless Pursuit of Frontier Parity
Over the past two years, the AI ecosystem has operated on a distinct bifurcated trajectory. On one side stood proprietary labs pouring unprecedented compute into closed flagship models, setting the high-water mark for complex reasoning and multimodal tasks. On the other side stood Meta, acting as a disruptive force by democratizing foundational capabilities and proving that open research ecosystems could rapidly close the performance gap. Yet, as software teams began transitioning from simple retrieval-augmented generation (RAG) to sophisticated agentic workflows, the performance delta between consumer-grade models and true frontier-tier architectures became increasingly noticeable.
Bridging that gap requires more than incremental fine-tuning; it demands vast infrastructure investments, refined data curation pipelines, and novel training paradigms. Meta's latest offering demonstrates that the social media giant is fully intent on standing shoulder-to-shoulder with the absolute best in the industry. By competing at the highest tiers of mathematical reasoning, long-context comprehension, and autonomous tool interaction, the release reaffirms that frontier-scale competition is far from a one- or two-horse race. More importantly, it brings top-echelon computational intelligence into an architectural paradigm where developers have greater latitude to build and iterate.
Taming Autonomous Behavior: The Agentic Bottleneck
While language models have excelled at isolated query-response interactions, the modern developer landscape has pivoted toward autonomous agents—systems empowered to execute command-line instructions, query APIs, manipulate database records, and string together dozens of interdependent decisions. However, this autonomy has introduced an acute failure mode: agentic drift. In production environments, an agent that misinterprets an intermediate tool output or compounds an early hallucination can quickly spiral into catastrophic execution loops, consuming rate limits, generating garbage data, or attempting unauthorized actions.
Meta’s new model directly addresses this systemic vulnerability. By integrating specialized training objectives and architectural safeguards designed to suppress out-of-bounds agentic drift, the model emphasizes deterministic adherence to tool constraints and verification protocols. Rather than assuming the model's generated plan is unconditionally valid, the underlying systems appear tailored to encourage self-monitoring, validation loops, and structured output formatting that dramatically reduce execution errors. For teams attempting to deploy automated assistants into live production software, these stability features transform agentic workflows from risky proof-of-concept experiments into commercially viable infrastructure.
Architectural Evolution: Beyond Raw Generative Fluency
The progression of foundation models is moving away from the era of pure statistical text prediction toward structured reasoning and goal-directed policy execution. Building a model that reliably directs autonomous agents involves teaching it how to pause, self-evaluate, and verify external tool feedback against its primary directive. In traditional architectures, an unexpected response from an integrated web search or SQL query often causes the agent to lose its context thread or invent imaginary parameters to force resolution.
To solve this, advanced frontier architectures leverage enhanced reinforcement learning and rejection sampling techniques focused on task trajectories rather than single-turn answers. The model is rewarded not just for finding a solution, but for recognizing when a sub-task has failed, gracefully backtracking, and adjusting its strategy without user intervention. By incorporating deliberate guardrails directly into the foundational weight space and decoding policies, developers are relieved from writing thousands of lines of fragile regex heuristics and defensive prompt chains just to ensure the model behaves predictably within an enterprise pipeline.
Implications for Software Engineers and System Architects
For software engineers building modern application stacks, this milestone alters several fundamental design assumptions. When foundation models can be trusted to adhere strictly to schema specifications, API boundaries, and role-based access parameters, the complexity of the accompanying orchestration framework shrinks considerably. Engineers spend less time debugging non-deterministic parser crashes and can focus instead on domain-specific tool interfaces and data quality.
Furthermore, reliable agentic capabilities alter how back-end services are constructed. Consider several practical shifts across the software lifecycle:
- Automated Code Remediation: Agents can be tasked with identifying failing unit tests, analyzing stack traces, drafting patches, and verifying that the build passes across complex monorepos without risking rogue repository operations.
- Resilient Microservice Orchestration: Rather than hardcoding rigid procedural workflows, developers can deploy autonomous coordinators capable of handling dynamic retries, schema mismatches, and intermittent network failures across internal APIs.
- Enterprise Governance and Compliance: Native containment guardrails make it significantly easier to audit automated decisions and prove compliance with strict data protection and operational safety regulations.
The Open vs. Closed Frontier Dynamics
Beyond individual developer workflows, Meta’s resurgence at the bleeding edge forces a recalibration of the broader artificial intelligence economy. When state-of-the-art capability is concentrated exclusively within closed commercial APIs, the software industry faces distinct vendor lock-in risks, escalating inference pricing, and opaque policy modifications. Organizations in highly regulated sectors—such as finance, healthcare, and telecommunications—often find themselves unable to deploy proprietary cloud-only endpoints due to strict data sovereignty constraints.
By advancing frontier capabilities and simultaneously providing enterprise-friendly operational models, Meta puts downward pressure on API pricing across the entire market while accelerating open innovation. Teams that previously relied on closed frontier models as their default reasoning engine now have a viable alternative that can either be self-hosted on private accelerators or accessed via multi-cloud hosting partners. This competition fosters a healthier technological substrate where no single corporate entity dictates the standards of autonomous computation.
The Path Toward Production-Grade Autonomy
The arrival of Meta's latest frontier powerhouse underlines a maturing phase for the AI industry. The initial excitement surrounding conversational fluency has settled into a pragmatic focus on operational reliability, verifiable reasoning, and robust autonomous action. As foundation models take on real responsibilities within the global software ecosystem, the metric of success is no longer how fluently a model writes, but how securely and predictably it acts. By prioritizing guardrails that keep autonomous systems on track, this new generation of models marks a definitive step toward AI agents that engineers can confidently trust in production.
Source: wired.com